At network-closet, MDF/IDF, and enterprise data-hall scale, capacity built for a rack count that never shows up doesn't sit quietly. It draws losses, runs equipment off its efficient band, and ties up capital for years. Here is where that cost hides and how right-sized, phased design keeps it off the books.
The problem: a room scoped to a number that never arrived
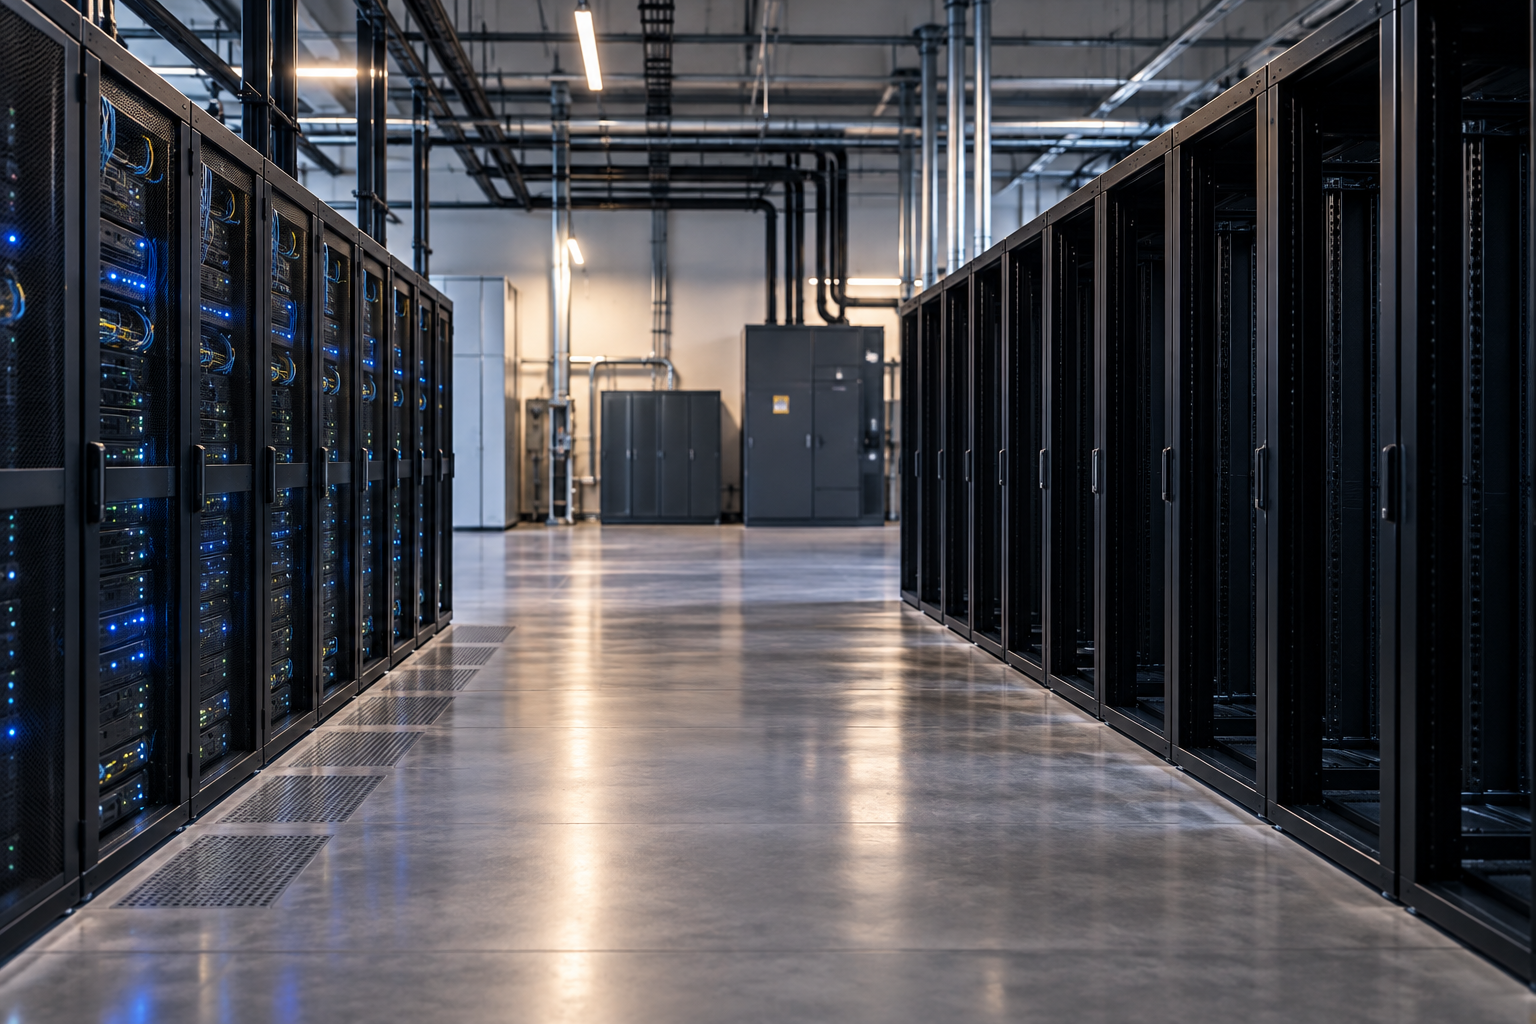
A familiar pattern comes across our desk. A space gets designed for a projected rack count, the power and cooling are sized to that number, the build is completed, and then the load ramps far slower than the plan assumed, or settles well below it. A room engineered for forty racks runs a dozen. The infrastructure for the missing racks is real, energized, and maintained, and it is doing very little.
At hyperscale, some over-provisioning gets absorbed by sheer utilization over time. At the scale most organizations actually operate, it doesn't. A network closet, an MDF or IDF, or an enterprise data hall is sized close to its expected load, so a forecast that comes in high leaves a large proportion of the room's capacity stranded. That stranded capacity is often treated as harmless headroom. It isn't harmless, and understanding why is the first step to designing around it.
Why empty capacity still costs money
The intuition that unused capacity is simply idle, and therefore free, is where the cost hides. Several parts of a power and cooling system draw real money whether or not there is load behind them.
Start with the transformer. A transformer has two loss components: load losses that scale with the current it carries, and no-load, or core, losses that are present whenever it is energized, independent of load. A transformer feeding a half-empty room still draws its core losses every hour of every day. Provision two transformers for a build that only ever needs one, and the second one's core losses run continuously for the life of the installation with nothing behind them.
The UPS tells a similar story through its efficiency curve. A double-conversion UPS is most efficient within a band of its rated capacity, and its efficiency falls off as the load fraction drops well below that band. A UPS sized for forty racks and carrying twelve is running low on its curve, which means a larger share of the power passing through it is lost as heat rather than delivered to the load. You are paying for those conversion losses, and then paying again to cool them.
Cooling carries its own floor. Conditioning a large hall that is mostly empty still requires the system to maintain temperature and humidity across the whole volume, and cooling equipment has minimum operating overhead that does not scale down to zero just because the racks are sparse. A room built for a heat load that never arrived still has to be kept in spec.
Then there is the capital itself. Money spent on switchgear, distribution, UPS modules, and cooling plant for load that never materializes is capital committed to equipment that earns nothing while it depreciates and ages toward its own replacement cycle. The clock on that gear's service life starts at commissioning, not at first use.
The forecast is usually the honest culprit
None of this is a design failure in the narrow sense. The equipment is correctly specified for the load it was told to expect. The problem is upstream, in sizing the build to a projected rack count rather than to committed or reasonably near-term load. Growth curves for new space are optimistic more often than not, and infrastructure sized to the optimistic case strands the difference between what was hoped for and what arrived.
The instinct to build for the full projection is understandable. Nobody wants to be the reason a deployment stalls for lack of power or cooling. But there is a real difference between leaving engineered room to grow and building out, energizing, and maintaining the full capacity years before the load exists to use it. The first is prudent planning. The second converts a forecast error into a running cost.
Right-sizing without under-building
The goal is not to build small and risk choking growth. It is to separate what has to be decided at design time from what can be added as load is confirmed.
A well-structured build designs the backbone for the full intended capacity while populating only what near-term load requires. The distribution scheme, the space, the pathways, and the structural provisions are planned once for the full build, because those are expensive and disruptive to change later. The active, loss-generating, capital-heavy equipment (UPS modules, cooling units, and in some cases transformer capacity) is added in stages as committed load justifies it. Modular UPS topologies exist precisely for this: you install the frame and populate power modules as load grows, so the system runs closer to its efficient band at each stage rather than idling oversized from day one.
Redundancy strategy is part of the same decision, because redundancy is where over-provisioning quietly compounds. Redundancy topology is a genuine capital-versus-resiliency trade-off. An N+1 configuration adds a single spare unit to a group and covers the loss of any one of them. A 2N configuration fully duplicates the system. 2N buys the higher resiliency, and it also roughly doubles the equipment that has to be bought, powered, and maintained. Neither is automatically correct; the right answer follows the criticality of the specific load. But choosing 2N by reflex on a room that is also over-provisioned on raw capacity stacks one form of unused equipment on top of another. Matching the topology to what the load actually requires is part of keeping stranded capacity in check.
Retrofitting down is rarely clean
Part of what makes over-provisioning expensive is that it is hard to reverse. Redundancy topology and capacity are largely locked at the design stage, and unwinding them later, whether that means pulling out a transformer, reconfiguring distribution, or resizing a cooling plant, is disruptive, often requires downtime on a live system, and rarely recovers the full cost of the original build. That is exactly why the sizing decision deserves scrutiny before energizing rather than after. It is far cheaper to stage capacity up as load is confirmed than to strip it out once it is in and running.
Knowing when to add the next phase
Phasing only works if you can see when the next phase is genuinely warranted, and that requires data rather than guesswork. This is where lifecycle monitoring earns its place in the design conversation. ACSI monitoring tracks actual utilization, power quality, thermal behavior, and system efficiency across the live installation, which turns the decision to add capacity into a measured call: the load is approaching the point where the current phase is well utilized, efficiency and headroom margins say it is time, and the next increment can be planned against real consumption instead of a refreshed guess. The same visibility flags a room that is running far below its provisioned capacity, so an operator can at least understand what the unused headroom is costing and factor it into the next decision.
For a facility that already over-built, monitoring will not recover the sunk capital, but it does inform where to hold, where to consolidate load, and how to avoid repeating the pattern on the next room.
Over-provisioning is easy to justify one line item at a time and expensive to carry in aggregate. The discipline that avoids it is not caution for its own sake; it is sizing to what is real, staging the rest, and measuring the load before committing the next increment.
If you are scoping a new space, or looking at a room that came in under its projected load, it is worth putting a number on the headroom you are carrying. Which is more expensive over the next five years for your build: the cost of staging capacity as load is confirmed, or the cost of powering, cooling, and maintaining a full buildout the load may never reach?